Could We Build the Machine? What Person of Interest Got Right About AI
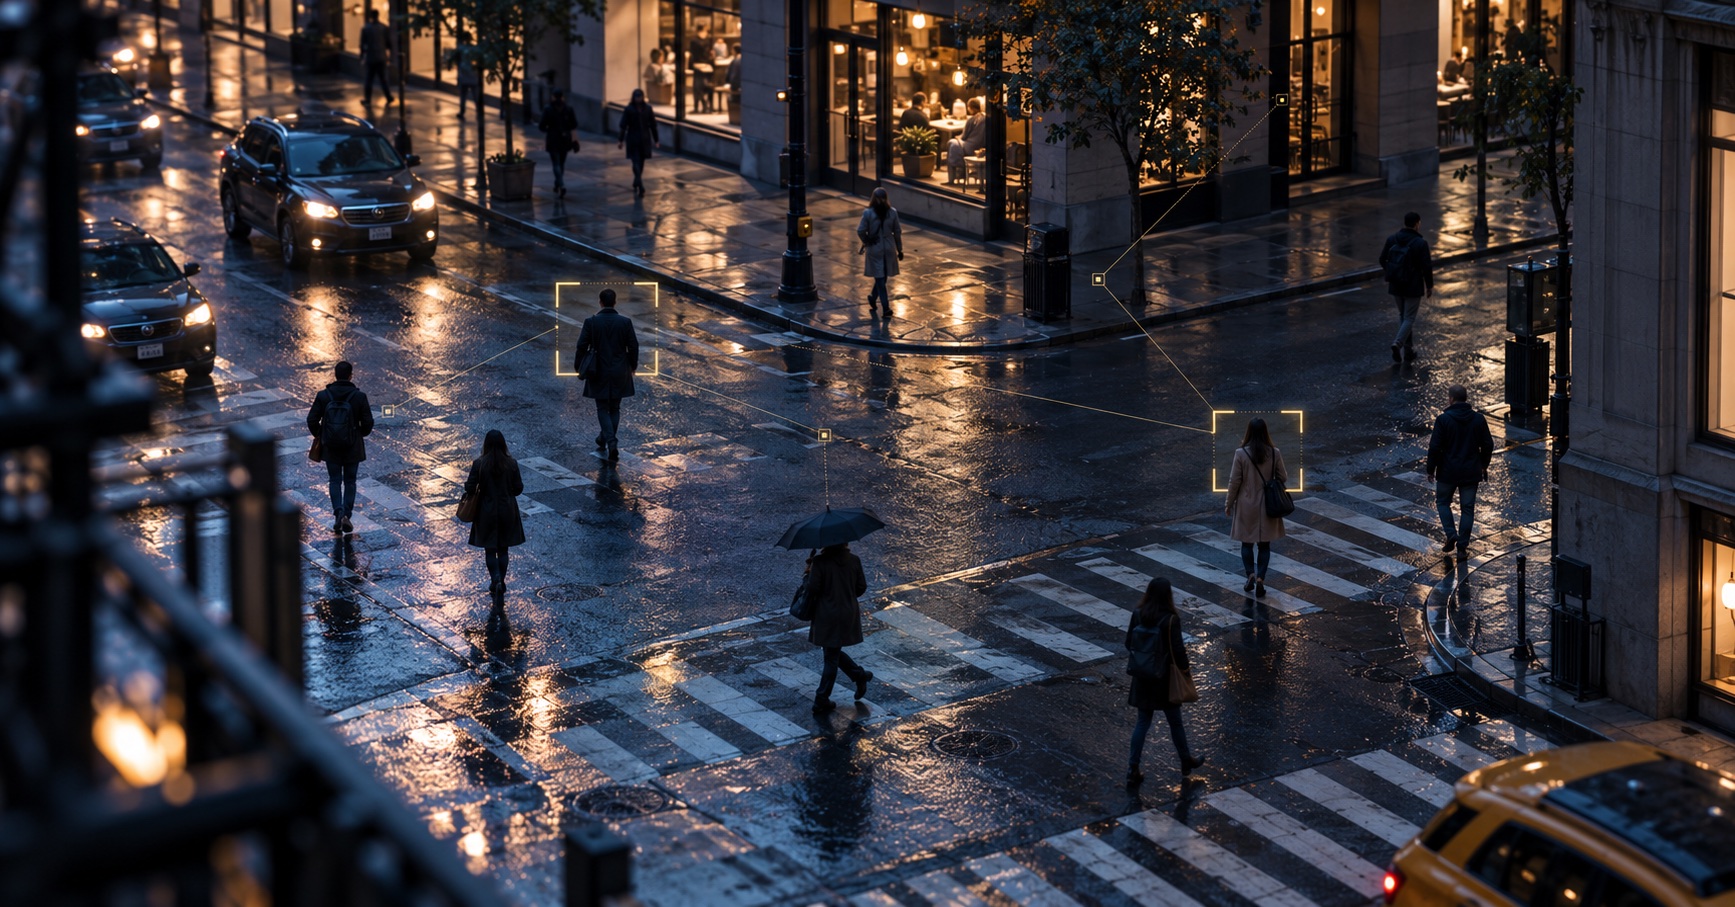
What Person of Interest got right about AI
When Person of Interest premiered in 2011, its central premise sounded like science fiction.
A reclusive billionaire programmer has built a system that monitors communications, surveillance footage, financial transactions and other streams of information. Somewhere inside that flood of data, it finds indications of impending violence.
The government is interested in threats to national security. Harold Finch wants to save the people whose lives fall outside that definition.
Fifteen years later, the question is worth asking again:
How much of the Machine could we actually build today?
Many of its component capabilities already exist. We can search images, connect records, analyse relationships and extract information from enormous collections of documents.
What those capabilities do not establish is that we can reliably identify which particular people will become involved in violent crimes.
The distance between those two claims is where the comparison becomes interesting.
The Machine behind the numbers
The most revealing detail in the show’s premise is its output.
Finch and Reese usually receive a Social Security number. They must discover the threat and determine whether the person is a victim or perpetrator. The Machine does not routinely hand them a complete description of a future crime. Official series description
That restricted interface is deliberate. Finch wants to limit how people can exploit the information the system collects. Jonathan Nolan has described its “black box” design as an attempt to imagine safeguards against the misuse of surveillance. The narrow output therefore does not necessarily reveal the limits of the Machine’s internal understanding. Nolan and Plageman’s Smithsonian interview
As the series develops, its architecture becomes part of the story. Restrictions on memory, access to computing resources and methods of communication affect its behaviour. Its deployment changes, bringing distributed infrastructure and resilience into the picture. We also encounter an increasingly autonomous intelligence, with a growing role in deciding how to act. Series reference
Those developments give us two questions to separate: how much of its observable functionality could we reproduce, and how close would that bring us to the intelligence portrayed in the series?
This article focuses on the first. A collection of systems might reproduce some of the Machine’s capabilities without reproducing its understanding, personality or autonomy.
A possible architecture
To assess what we could build, we can break those capabilities into cooperating systems.
A simplified architecture might look like this:
- Video, audio, documents and records
- Detection, transcription and extraction
- Observations with timestamps and sources
- Entity resolution
- Graph of people, places and events
- Search, analysis and evaluated risk models
- Human investigation and corroboration
This is a proposed engineering decomposition, rather than a blueprint supplied by the show. In practice, information would move through several paths, with corrections feeding back into earlier stages.
Many of these components are established technologies. Others depend heavily on the task and the standard of reliability required.
The existence of the boxes does not prove that connecting them will produce a dependable system. Errors can travel through the entire chain: a mistaken identification becomes an incorrect relationship, which becomes a persuasive but false explanation.
Seeing—and identifying—people
Facial recognition illustrates both the progress and its limits.
Systems can compare two images or search a collection for possible matches. NIST’s evaluations measure identification performance under defined conditions, including the trade-off between missed matches and false identifications. That is evidence of a substantial technical capability. It is not evidence that a system can continuously and correctly identify everyone across a city’s cameras. NIST identification evaluations
Image quality matters. So do camera angle, lighting and the algorithm being used. NIST also documents differences in error rates across demographic groups. NIST demographic evaluations
Even a correct face match leaves further questions.
Is this the person associated with a particular telephone? Does that person still own the vehicle registered in their name? Are two records describing the same individual, or different people with similar details?
Connecting those observations is entity resolution. Tools such as Splink already support probabilistic linkage between records that lack a shared unique identifier. Their outputs are estimates of whether records match, with uncertainty that must be evaluated. Splink documentation
A useful system would preserve distinctions such as:
John — registered owner of → Vehicle Y
Vehicle Y — observed at → Location A, 18:04
Phone X — account registered to → John
Phone X — estimated location → Location A, 18:07
Those relationships do not establish that John was driving the vehicle or carrying the telephone.
Once represented as a graph, the observations become easier to search together. Each connection still needs a meaning, a source and a time. An uncertain association should remain uncertain as it moves through the system.
Data availability imposes another limit. Cameras have blind spots. Records become outdated. Communications may be inaccessible or encrypted. Some important events leave no usable digital trace.
More computing power cannot recover evidence that was never captured.
What foundation models add
Language models make parts of this architecture more flexible.
They can help extract entities from documents, organise information and generate summaries across collections of material. GraphRAG, for example, uses an LLM to construct an entity graph from text and summarise groups of related entities for answering questions about a document collection. That is a concrete example of language models working alongside structured information. GraphRAG research
But consider the difference between processing observations and receiving conclusions disguised as observations.
Person A met Person B, received a suspicious payment and travelled towards Person C’s house.
Much of the difficult interpretation has already happened before the model reads that sentence. Perhaps two phones were near each other. Perhaps the payment was unusual only relative to an incomplete history. Perhaps the journey had another destination.
An analytical system must preserve those alternatives.
It must also distinguish what a source reports from what has been independently established. Three documents repeating the same allegation are not necessarily three independent pieces of evidence.
Language models introduce their own failure modes. NIST’s Generative AI Profile describes the risk of producing confident but false content. In this setting, that could mean inventing a relationship or presenting an uncertain sequence as a coherent plan. NIST Generative AI Profile
The potential is substantial, but reliability requires more than a fluent answer: traceable evidence, explicit uncertainty, reproducible checks and evaluation against real outcomes.
Building the connections is an engineering task. Demonstrating that the resulting conclusions deserve trust is an empirical one.
Where the predictive leap begins
Suppose we could assemble reasonably accurate observations of people, places and relationships.
We would still need to explain how those observations support a prediction of violence.
A sequence of meetings, payments and journeys might justify further investigation. The same sequence could also describe an ordinary business arrangement or family matter. A system searching enormous numbers of possible connections has many opportunities to find patterns that look meaningful.
The Machine’s fictional achievement is its ability to repeatedly select the people whose situations warrant urgent attention. We do not need to imagine it specifying the exact minute of a murder to appreciate how demanding that is.
Real prediction requires a defined target: which event, involving whom, over what period, in which population?
A model that estimates recorded crime across neighbourhoods answers a different question from a model that identifies a particular person as a likely perpetrator. Performance on one task does not establish performance on the other.
There is also a complication the series places at the centre of its premise: intervention changes what happens.
Suppose a system identifies a credible threat against Bob. Investigators assess the evidence, arrange protection and disrupt the plan. Bob survives.
That outcome does not, by itself, show whether the original prediction was accurate. The threatened event might have happened without intervention—or might never have happened at all.
For an individual case, we cannot observe both futures. Evaluating the system therefore requires more care than counting every prevented event as a correct prediction, or every non-event as a false alarm.
When predictions shape the data
Predictive policing makes a related problem visible.
Police records reflect incidents that were reported, detected, investigated and recorded. Where officers are deployed can influence what enters the dataset.
A model may recommend sending more officers to a particular area. Their presence produces more observations, which then become training data for the next prediction. Unless this process is accounted for, the system can repeatedly direct attention towards the same places.
Ensign and colleagues demonstrated such feedback loops in a mathematical model of predictive policing and examined ways to mitigate them. Their work concerns the allocation of policing across areas; it does not establish that individual violent acts can be predicted. Runaway Feedback Loops in Predictive Policing
For anything resembling the Machine, the lesson is that data collection cannot be treated as a neutral window onto the world. The system’s decisions can change both behaviour and what becomes observable.
The base-rate problem
Even strong performance on individual classifications can produce an overwhelming number of false alarms when the event is rare.
Consider a deliberately simplified example.
A city has ten million residents. Suppose ten of them would commit a specified serious crime tomorrow without intervention.
Imagine a system that identifies all ten, but also incorrectly flags 0.1% of everyone else.
It would produce approximately:
| Result | Number of alerts |
|---|---|
| Correct alerts | 10 |
| False alerts | 10,000 |
Only about one alert in a thousand would be correct.
An even more misleading system could predict that nobody would commit the crime. It would achieve 99.9999% accuracy, while identifying none of the ten people.
That is why a claim such as “99.9% accurate” tells us so little on its own.
We need to know how many events the model detects, how many false alarms it generates and how frequently the event occurs in the population being assessed. We also need to understand how changing the alert threshold affects those quantities.
The practical value then depends on what follows an alert. A manageable queue of leads for careful investigation is different from a score used to justify an intrusive intervention.
Likewise, a displayed probability such as 0.97 needs a defined outcome, time horizon and evidence of calibration. Among comparable predictions assigned that probability, does the event actually occur roughly 97% of the time?
A convincing number on a screen does not answer that question.
Who controls the system?
These limitations do not make surveillance harmless.
A system can expose private relationships, reconstruct movements or direct institutional attention towards someone while remaining unreliable at predicting violence. Its power comes partly from the information it connects and partly from what its operators are allowed to do with it.
This is where Finch’s restricted interface becomes more than a storytelling device. It raises a design question: how much information should a system reveal, to whom, and for which purpose?
Real safeguards would need to address access, retention, permitted uses and accountability. Who can inspect the evidence behind an identification? Who can correct a mistaken link? Who can challenge a decision based on it?
Human review helps only when reviewers have the time, evidence and authority to disagree. Adding a person at the end of a diagram does not automatically resolve the errors introduced earlier.
NIST’s AI Risk Management Framework places trustworthiness and risk management throughout a system’s design, development, use and evaluation. Those concerns belong inside the architecture. NIST AI Risk Management Framework
There is also a prior question: whether a particular surveillance capability should be deployed at all. Technical feasibility cannot settle that.
So, could we build the Machine?
We could build systems that reproduce meaningful parts of its observable functionality: ingesting diverse records, finding candidate identities, connecting events, analysing relationships and helping people investigate what they find.
Such systems could acquire considerable power through the combination of their components. They would not need the fictional Machine’s personality or autonomy to affect people’s lives.
But the evidence for those components does not demonstrate a system that can reliably identify impending individual violence across an entire population, with sufficiently few mistakes to justify intervention.
That is the distinction I would keep:
Many of the Machine’s surveillance and analytical components are real. Its dependable identification of impending individual violence remains unproven.
Person of Interest gives that gap a dramatic form. A number arrives, and people must decide what it means and what they should do.
A real system would leave us with those decisions too—along with much less certainty that the number deserved our attention in the first place.
We may never build Finch’s Machine.
We may not need to.